Ao Li

Ao Li 李奡

Embodied AI Human–Robot Interaction

Portrait of Ao Li

I’m a master’s student in artificial intelligence at Tsinghua University, where I work with my advisors, Prof. Yansong Tang and Prof. Jiwen Lu, in the THU-IVG Lab. I earned my B.S. in artificial intelligence from Beijing Normal University in 2024.

As a research intern at JD Joy Future Academy, I study how robots can learn manipulation skills from first-person videos of people performing everyday tasks. I’m a core contributor to JoyAI-RA 0.1/0.5, a series of foundation models for robot manipulation.

Previously, at Tencent Robotics-X, I worked with Dr. Yonggen Ling on TAIHRI (ECCV 2026), a vision-language model that helps a robot identify which part of a person’s body to attend to when following a motion command.

News

  • Our preprint TouchAnnotator is available on arXiv.
  • Our preprint EgoForesight is available on arXiv.
  • JoyAI-RA 0.5 was released! See our technical report for more details.
  • JoyAI-Sim was released! See our technical report for more details.
  • One paper on Human-Robot Interaction was accepted to ECCV 2026.
  • JoyAI-RA 0.1 was released! See our technical report for more details.
  • One paper on Efficient Image Enhancement was accepted to ICLR 2026.
  • One paper on Human-Object Interaction Reconstruction was accepted to ICCV 2025.
  • One paper on Efficient Image Enhancement was accepted to ICLR 2025.
  • Invited as a Spotlight Presenter at the MANGO workshop at CVPR 2024.
  • Our work FlowIE was selected for an oral presentation at CVPR 2024!
  • Two papers on Human Mesh Recovery and Image Enhancement were accepted to CVPR 2024.

Education

Sep 2024 – Jun 2027

Tsinghua University

M.S. in Artificial Intelligence

Shenzhen International Graduate School

Sep 2020 – Jun 2024

Beijing Normal University

B.S. in Artificial Intelligence

School of Artificial Intelligence

Industry Experience

Mar 2026 – Present · Shenzhen, China

JD Joy Future Academy

Egocentric human videos for VLA/WAM pretraining.

Working with Dr. Zhihao Yuan.

May 2025 – Mar 2026 · Shenzhen, China

Tencent Robotics-X

VLM for human-robot interaction.

Worked with Dr. Yonggen Ling.

Selected Publications

Grouped by research topic. Highlighted roles indicate first authorship or core contributions.
* Equal contribution  ·  # Corresponding author

Embodied AI, Human-Robot Interaction

Embodied foundation models, interactive perception, and reconstruction
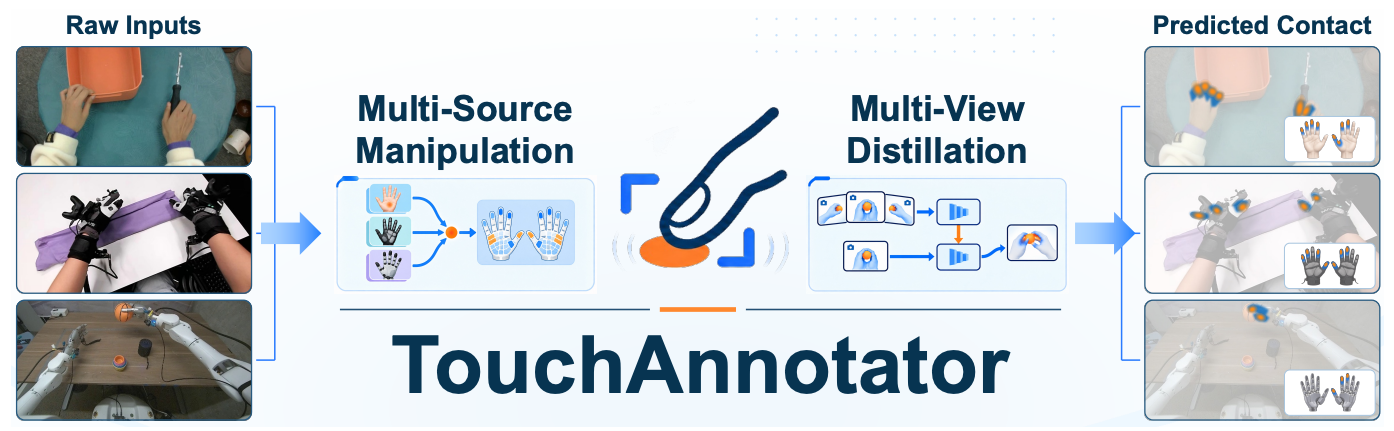
Egocentric inputs and schematic contact maps for human and robot hands.
Co-first Author

TouchAnnotator: Multi-Source Tactile Supervision with Privileged-View Distillation

Ao Li*, Zhihao Yuan*, Chubin Zhang, Kunrui Huang, Sheng Xu, Zengjue Chen, Junjie Wang, Jiawei Li, Yansong Tang#

arXiv, 2026

TouchAnnotator predicts where each hand makes contact and how pressure varies from first-person video and estimated hand pose.

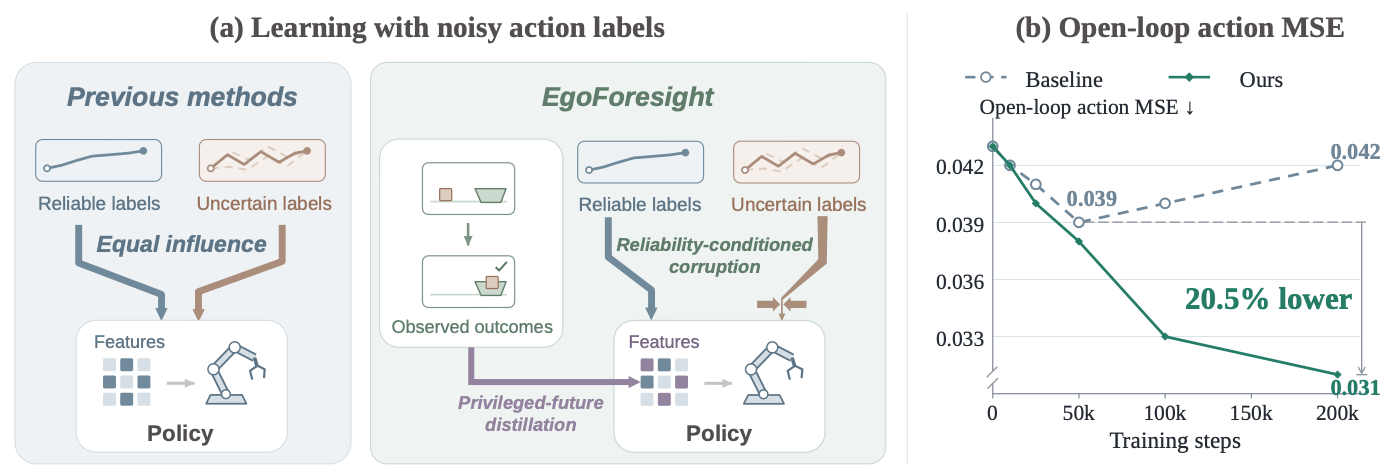
Reliability-aware action supervision and open-loop action error over training.

EgoForesight: Effectively Scaling Policy Learning with Noisy Egocentric Actions

Chubin Zhang, Changyuan Wang, Yirui Wang, Ao Li, Shilin Ma, Yue Su, Cai Zhou, Xiuwei Xu, Tianle Zhang, Yansong Tang#

arXiv, 2026

EgoForesight learns robot policies from demonstrations and first-person human video. It weights action labels by their reliability and uses what happens next in the video to help predict actions.

JoyAI-RA 0.5 research figure.
Core Contributor

JoyAI-RA 0.5: Scaling Robot Manipulation Learning via Dual Action Alignment

JD Joy Future Academy (core contributor)

arXiv, 2026

A generalist Vision-Language-World-Action (VLWA) framework that couples physical world-dynamics priors with visual semantics and scales manipulation learning across such data via dual action alignment.

JoyAI-Sim research figure.
Core Contributor

JoyAI-Sim: A Simulation-Enabled Interconversion Toolchain for the Embodied Data Pyramid

JD Joy Future Academy (core contributor)

arXiv, 2026

A simulation data transformation toolchain, Robot ⇌ Simulation ⇌ Human, built upon the embodied data pyramid.

JoyAI-RA 0.1 research figure.
Core Contributor

JoyAI-RA 0.1: A Foundation Model for Robotic Autonomy

JD Joy Future Academy (core contributor)

arXiv, 2026

A vision-language-action (VLA) embodied foundation model tailored for generalizable robotic manipulation.

TAIHRI research figure.
First Author

TAIHRI: Task-Aware 3D Human Keypoints Localization for Close-Range Human-Robot Interaction

Ao Li*, Yonggen Ling*, Yiyang Lin, Yuji Wang, Yong Deng, Yansong Tang

European Conference on Computer Vision (ECCV), 2026

We propose TAIHRI, the first vision-language model (VLM) tailored for close-range HRI perception, capable of understanding users' motion commands and directing the robot's attention to the most task-relevant keypoints.

Human Pose Understanding, Human-Object Interaction

Robust 3D human representation under occlusion

ScoreHOI research figure.
First Author

ScoreHOI: Physically Plausible Reconstruction of Human-Object Interaction via Score-Guided Diffusion

Ao Li, Jinpeng Liu, Yixuan Zhu, Yansong Tang

IEEE International Conference on Computer Vision (ICCV), 2025

We propose ScoreHOI, a framework for human-object interaction reconstruction via score-guided diffusion to enhance the physical plausibility.

DPMesh research figure.
Co-first Author

DPMesh: Exploiting Diffusion Prior for Occluded Human Mesh Recovery

Yixuan Zhu*, Ao Li*, Yansong Tang#, Wenliang Zhao, Jie Zhou, Jiwen Lu

IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024

We propose a new method to exploit diffusion priors for human mesh recovery (HMR) in occlusion and crowded scenarios.

Efficient Image Restoration & Enhancement

Fast generative priors for image enhancement and super-resolution

VARestorer research figure.

VARestorer: One-Step VAR Distillation for Real-World Image Super-Resolution

Yixuan Zhu*, Shilin Ma*, Haolin Wang, Ao Li, Yanzhe Jing, Yansong Tang#, Lei Chen, Jiwen Lu, Jie Zhou

The Fourteenth International Conference on Learning Representations (ICLR), 2026

We introduce VARestorer, a one-step VAR distillation framework for real-world image super-resolution that mitigates error accumulation.

InstaRevive research figure.

InstaRevive: One-Step Image Enhancement via Dynamic Score Matching

Yixuan Zhu, Haolin Wang, Ao Li, Wenliang Zhao, Yansong Tang, Jingxuan Niu, Lei Chen, Jie Zhou, Jiwen Lu

The Thirteenth International Conference on Learning Representations (ICLR), 2025

We propose InstaRevive, a straightforward yet powerful image enhancement framework that employs score-based diffusion distillation to leverage strong generative capabilities and reduce the number of sampling steps.

FlowIE research figure.

FlowIE: Efficient Image Enhancement via Rectified Flow

Yixuan Zhu, Wenliang Zhao, Ao Li, Yansong Tang#, Jie Zhou, Jiwen Lu

IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024 · Oral Presentation

We propose a unified framework for various efficient image enhancement tasks with generative diffusion priors.

Selected Honors and Awards

  • First-Class Scholarship (Top 3%), Tsinghua University, 2025.
  • Second Prize, Science and Technology Progress Award, China Society of Image and Graphics (CSIG), 10th listed contributor.
  • Outstanding Bachelor Graduate of Beijing, 2024.
  • "Jingshi" First-Class Scholarship (Top 10%), Beijing Normal University, 2021-2023.
  • Potential Star Award - Meituan Second Low-Altitude Economy UAV Management Challenge (Innovation Track), 2024.

Academic Service

Conference Reviewing

I have reviewed papers for conferences including ICLR and AAAI.

Journal Reviewing

Journal of Visual Communication and Image Representation (JVCI)

Teaching Assistant

  • Fall 2026–2027 Frontiers and Interdisciplinary Applications of Deep Learning (深度学习前沿与交叉)
  • Spring 2025–2026 Reinforcement Learning (强化学习)
  • Fall 2025–2026 Frontiers and Interdisciplinary Applications of Deep Learning (深度学习前沿与交叉)